Why Legacy CSS Accordions Block Google AI Overviews and How HTML5 Details Tags Restore FAQ Citations
Published November 13, 2026 · Last reviewed November 13, 2026
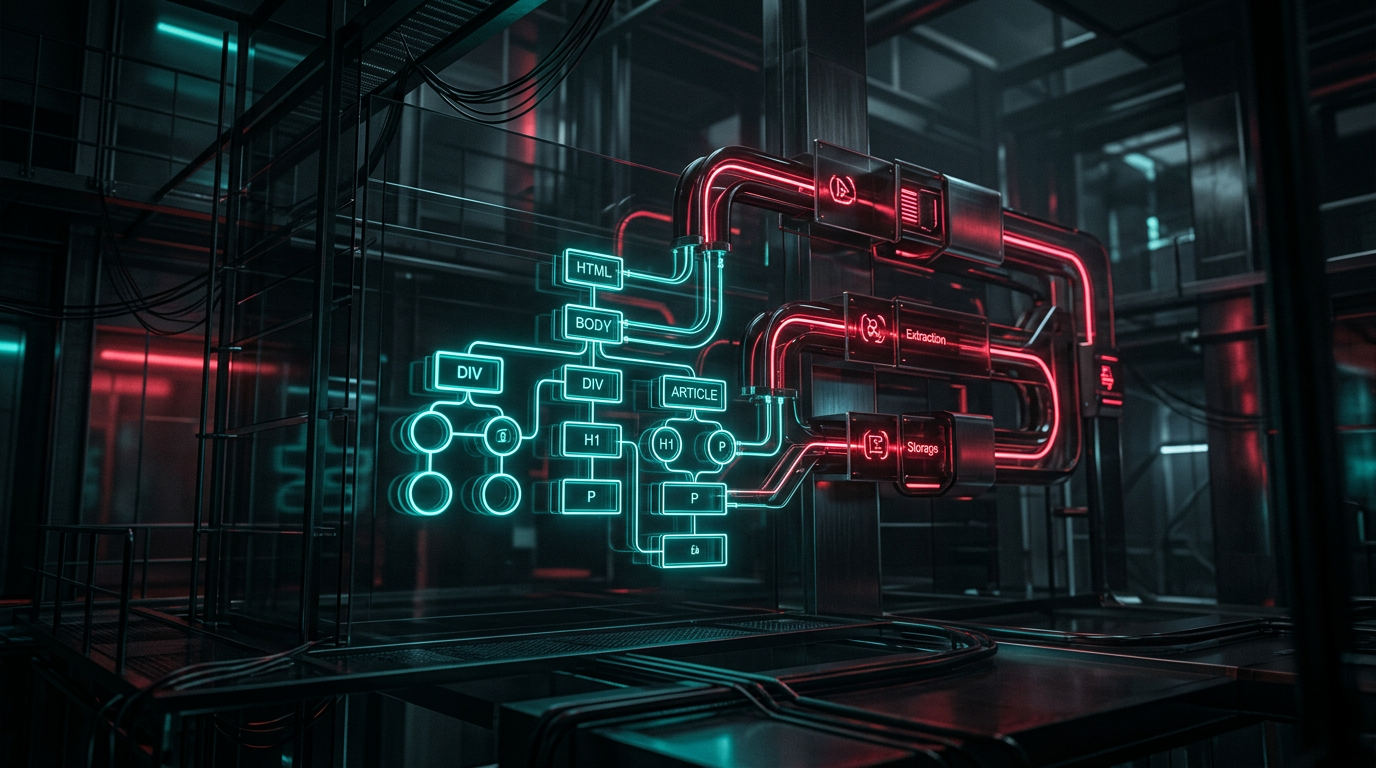
High-intent landing pages and resource hubs often bury critical objection handling, pricing nuances, and technical specifications inside interactive accordion widgets. When paid traffic teams and organic search teams audit why competitor sites capture citations in Google AI Overviews while their own authoritative answers disappear, the culprit is frequently the Document Object Model architecture. Hiding text behind legacy Cascading Style Sheets rules like display:none creates a retrieval penalty during AI snippet generation.
For an operator spending tens of thousands of dollars each month to acquire qualified buyers, losing top-of-page real estate in search answer engines directly inflates customer acquisition costs. Fixing this layout pattern requires modernizing the underlying HyperText Markup Language so automated retrieval models can ingest every answer without altering visual design.
The short answer
Legacy accordion menus hiding content behind CSS display:none or visibility:hidden properties prevent Google AI Overviews from prioritizing expandable answers. While Googlebot executes JavaScript and parses standard Document Object Model trees, AI Overview extraction pipelines prioritize immediately accessible text and semantic markup. Replacing style-hidden containers with native HTML5 details and summary elements, or using the hidden="until-found" attribute, exposes content to the browser find-in-page mechanism and LLM extraction layers without breaking user interface design.
Why CSS-hidden containers fail AI retrieval pipelines
Googlebot has rendered JavaScript and indexed content hidden behind CSS tabs and accordion toggles for years. However, indexing a URL for traditional blue links differs significantly from the passage extraction pipeline used by Google Search Central documentation on AI features and generative summaries. Large language models and secondary passage-ranking algorithms score content based on document structure, semantic hierarchy, and accessibility.
When content is wrapped in a generic div tag styled with display: none or visibility: hidden, search rendering engines deprioritize the text during initial passage scoring. The crawler recognizes that the element is not rendered on screen during the initial viewport calculation. In generative answer pipelines, content that appears invisible to standard users receives a lower semantic confidence score compared to visible, high-prominence body copy.
This architecture creates a secondary issue: search bots from alternative platforms frequently bypass client-side JavaScript rendering altogether to save compute resources. As documented in our analysis of how OAI-SearchBot handles rendering, answer engine bots that do not execute multi-stage JavaScript layouts completely ignore interactive accordions that require click event listeners to inject text into the DOM.
| Technical Implementation | Googlebot Full Indexing | AI Overview Snippet Extraction | Find-in-Page Support | Semantic Document Structure |
|---|---|---|---|---|
CSS display: none |
Yes | Low confidence / Deprioritized | No | Low (Generic Divs) |
CSS visibility: hidden |
Yes | Low confidence / Deprioritized | No | Low (Generic Divs) |
HTML5 <details> and <summary> |
Yes | High priority / Native support | Yes | High (Standard Element) |
hidden="until-found" |
Yes | High priority / Native support | Yes | High (Accessible State) |
Restoring visibility with HTML5 details and hidden until found
Migrating away from legacy script-driven accordion components does not require abandoning collapsible user interfaces. The modern web platform provides two distinct, fully supported mechanisms for collapsing secondary content while keeping it completely visible to automated scrapers and screen readers.
Method 1: Semantic HTML5 details and summary tags
The standard <details> element provides native browser-level collapsing without requiring custom JavaScript state management. The W3C HTML Living Standard outlines how user agents handle details containers: the browser natively treats the text inside as part of the accessible document tree, while rendering only the <summary> element until toggled.
<details class="faq-item">
  <summary class="faq-question">What is the standard onboarding timeline for enterprise accounts?</summary>
  <div class="faq-answer">
    <p>Enterprise onboarding takes between fourteen and twenty-one business days, including data migration, Conversions API verification, and CRM field mapping.</p>
  </div>
</details>
Because the browser handles the open and closed states natively, extraction engines do not need to simulate click events or evaluate custom CSS classes to verify that the answer belongs to the header question.
Method 2: The hidden="until-found" attribute
For engineering teams maintaining custom animated accordion libraries, Chromium and other modern rendering engines support the hidden="until-found" attribute. Documented in the MDN Web Docs HTML attribute reference, this attribute signals to the browser that the container is collapsed visually but remains accessible to search indexing and the native browser find-in-page search function (Ctrl+F or Cmd+F).
<button aria-expanded="false" aria-controls="faq-answer-1" class="accordion-trigger">
  How does the attribution window handle cross-domain tracking?
</button>
<div id="faq-answer-1" hidden="until-found" class="accordion-panel">
  <p>Cross-domain tracking persists first-party identifiers across root domains using server-side session sync, preserving attribution up to ninety days.</p>
</div>
When a user or search scraper queries text inside an element marked with hidden="until-found", the browser automatically removes the hidden state and displays the target passage. This informs search engine ranking systems that the hidden content is directly relevant to user search queries rather than boilerplate footer text or obscured tracking elements.
Structured data integration and passage ranking
Replacing legacy CSS patterns solves the DOM accessibility problem, but answer engines also evaluate structured markup to confirm question-and-answer pairs. Applying valid Schema.org FAQPage structured data ensures that your FAQ content matches the visible document structure.
As Google refined its search snippet guidelines in early 2024, FAQPage rich results in standard search results were restricted primarily to authoritative government and health sites. However, Google AI Overviews and answer retrieval bots still use structured data as an ingestion map to identify clean text snippets for generative synthesis. Similar structural issues affect other landing page elements, as explored in our guide on div-based comparison tables in AI search engines.
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [{
    "@type": "Question",
    "name": "What is the standard onboarding timeline for enterprise accounts?",
    "acceptedAnswer": {
      "@type": "Answer",
      "text": "Enterprise onboarding takes between fourteen and twenty-one business days, including data migration, Conversions API verification, and CRM field mapping."
    }
  }]
}
To ensure maximum extraction efficiency, keep the plain text inside the JSON-LD script tag identical to the text rendered inside the HTML5 details element. Discrepancies between structured data and the visible DOM can trigger quality penalties under Google Search Essentials guidelines.
What this means if you're running spend
When marketing teams run paid search and programmatic traffic to mid-funnel landing pages, prospective buyers frequently conduct secondary research in Google before submitting a qualification form. They search for your brand alongside specific objections: contract length, integration limits, pricing tiers, and cancellation terms.
If your technical answers are trapped in legacy CSS accordions, Google AI Overviews will pull answers from third-party review sites, competitor comparison pages, or outdated forum threads instead of your official page. When the generative summary at the top of the search results answers an integration question incorrectly, that prospective lead drops out of the funnel before your sales team ever receives a lead notification in the CRM.
Upgrading your landing pages to semantic HTML5 details elements or hidden="until-found" containers requires minimal engineering effort but produces immediate downstream benefits:
- Search engines cite your authoritative documentation instead of competitor comparison landing pages.
- Inbound prospects arrive on demo calls with accurate expectations regarding product capabilities and implementation timelines.
- Organic search assisted conversions increase across high-intent product queries.
- Landing page accessibility scores improve, reducing page weight and Interaction to Next Paint latency on mobile devices.
Auditing your core offer pages, pricing pages, and product documentation for hidden CSS containers prevents paid search pipeline leakage across every active campaign.
FAQ
Does Google still index text wrapped in CSS display:none?
Googlebot indexes text styled with display:none for traditional search queries, but generative search systems and AI Overviews deprioritize hidden text during snippet extraction. Using native HTML5 details tags or the hidden="until-found" attribute ensures passage extraction algorithms treat the content with high confidence.
Will migrating to HTML5 details break custom accordion animations?
Modern CSS supports the ::details-content pseudo-element and transition properties on the details tag, allowing smooth height and opacity animations. Front-end engineers can style native details elements to match existing brand guidelines without relying on script-heavy wrapper libraries.
How does the hidden="until-found" attribute work across different browsers?
Chromium-based browsers natively support hidden="until-found" by expanding the element during browser find-in-page searches or scraper DOM passes. In browsers that have not yet implemented the specification, standard CSS fallback rules maintain standard collapsible functionality without breaking the page layout.
Does adding FAQPage schema replace the need for semantic HTML?
No. Structured data provides an ingestion hint, but search retrieval models verify schema against the rendered DOM tree. Relying on JSON-LD while hiding the underlying DOM elements with display:none can trigger structured data mismatch warnings and prevent citation extraction.
How much of this applies to your operation?
How much of this applies to your company depends on how your landing pages, qualification funnels, and technical product docs are structured. If your organic visibility and paid pipeline are leaking qualified prospects to competitor answer summaries, the underlying code architecture is often the root cause.
We review full-funnel marketing operations, from search visibility and ad infrastructure to CRM routing and offline conversion reconciliation. If you want an engineering team to inspect your tracking, landing page performance, and paid acquisition setup, apply to work with Fizzi Media to start the evaluation.
Last reviewed November 13, 2026. Sources linked inline.
Speak directly with Jason, our Managing Director. No sales reps.